
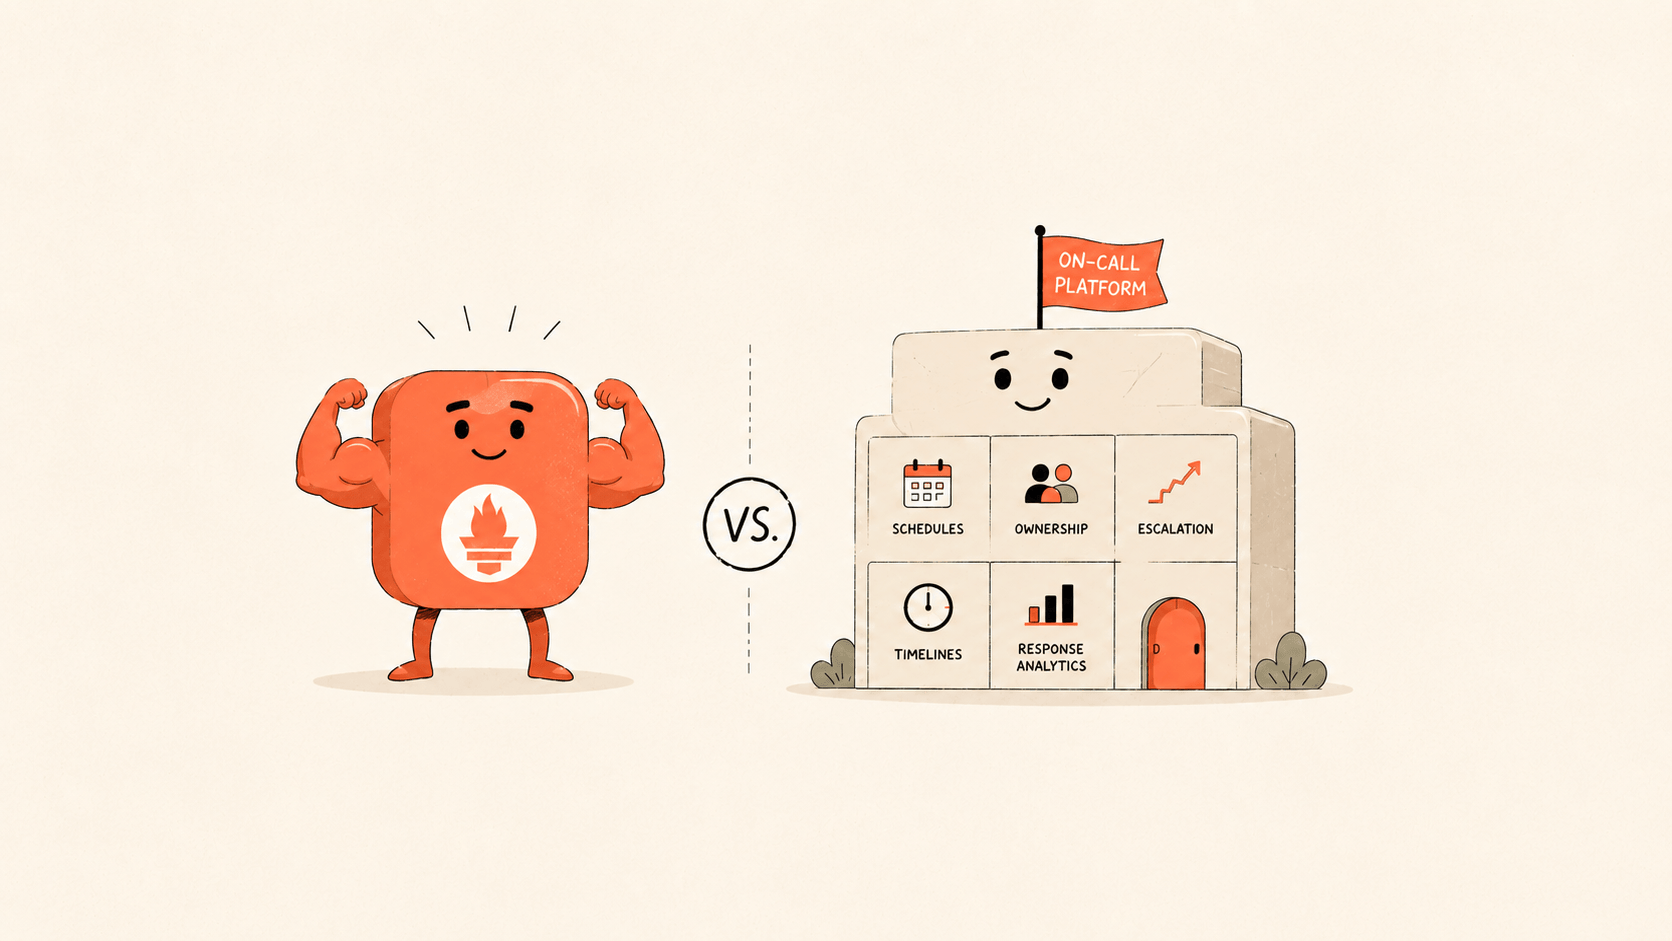
If you have one team, a few Prometheus instances, and alerts that someone handles as soon as they reach one chat group, Alertmanager is enough. Once you have several monitoring sources, need schedules and automatic escalation, or want to track MTTA, add an on-call platform after Alertmanager. You don't need to replace Alertmanager.
Alertmanager handles routing: which alert goes to which receiver under which conditions. An on-call platform handles response: who's on call, who acknowledged the incident, and what happens when nobody responds. It also records a timeline and shows leaders response metrics. This post starts with a comparison table and two checklists, then walks through five boundaries, and ends with setup steps.
The boundary in one table
| Dimension | Alertmanager | On-call platform |
|---|---|---|
| Multi-source ingestion | Prometheus-first; everything else via your own Webhook plumbing | Native connectors for many monitoring tools, cloud monitoring, logs, APM |
| Scheduling | No model of people; targets hard-coded in receivers | Rotating schedules with primary/backup, day/night shifts, swaps, fairness |
| Automatic escalation | None; an unanswered alert needs a human watching | Auto-escalate on unacknowledged/unclosed to backup or owner after N minutes |
| Noise reduction | Grouping, silencing, inhibition (stays at the alert layer) | Result lands on an incident object, plus intelligent grouping, storm warning, flapping detection |
| Collaboration and ack | Group-message notification; no managed state | Acknowledge from console / IM / voice call with a full incident timeline |
| Mobile | Depends on IM bot messages; actions require a laptop | App push plus acknowledge, comment, and close directly on mobile |
| Data-driven management | Config as documentation; no response metrics | MTTA/MTTR, response rate, interruption count, and responder-load dashboards |
| Cost and positioning | Open source, no license fee; positioned as alert aggregation | SaaS with a free tier; positioned as incident response management |
This table isn't about which tool is stronger. When your needs fall in the right-hand column, pushing more logic into Alertmanager's config files rarely makes things simpler.
When Alertmanager is enough
Keep Alertmanager as your main tool if your team fits these conditions:
- You have a few Prometheus instances and a small number of alert rules.
- Alert recipients are mostly fixed, so you don't need complex schedules.
- When an alert arrives, the team responds quickly in one chat group.
- You don't need primary and backup on-call, automatic escalation, or phone and SMS as a fallback.
- You don't need cross-team collaboration, ticket sync, status pages, or postmortems.
- You don't need MTTA, MTTR, or response effort by team, person, or service.
- A few people maintain the Alertmanager config, and its complexity is under control.
In that case, configure Alertmanager well and keep labels and rules clean. That's more practical than adopting a new platform too early.
Signs you need an on-call platform
Evaluate an on-call platform when you see these signs:
- Alerts come from more than Prometheus, such as Zabbix, Nightingale, Grafana, cloud monitoring, logs, APM, or internal systems.
- Several teams share one Alertmanager config, and routes and receivers are getting hard to maintain.
- Alerts often land in chat with no clear owner.
- Critical alerts need phone, SMS, app, and IM delivery.
- Schedules live in a spreadsheet, a chat announcement, or people's memory.
- When the primary doesn't respond, the alert needs to escalate to the backup or an owner automatically.
- During alert storms, responders get many duplicate notifications.
- You need MTTA, MTTR, response rate, interruption count, and responder load.
- After an incident, you need a timeline, a postmortem, tickets, or audit records.
If you keep pushing logic into Alertmanager at this point, your response process becomes hidden logic in config files. Maintenance cost and incident risk both go up. A safer approach is to keep Prometheus and Alertmanager and hand on-call response to a dedicated platform.
Five things Alertmanager does well
Alertmanager is the standard component in the Prometheus alerting stack. It receives alerts from Prometheus and handles them as follows:
- Deduplication: multiple Prometheus instances or identical alerts don't trigger endless repeat notifications.
- Grouping: similar alerts merge into one notification. For example, when many instances in a cluster can't reach the database, group by labels such as
clusterandalertname. - Routing: a routing tree sends alerts with different labels, severities, and owners to different receivers.
- Silencing: a silence stops notifications for a set time, for maintenance windows, known issues, or alerts that don't need a notification yet.
- Inhibition: when a higher-level failure occurs, related derived alerts are inhibited. For example, when a whole cluster is unreachable, connectivity alerts from services inside it are inhibited.
Among open-source options, people often compare Alertmanager with Zabbix. Zabbix's built-in PROBLEM management is quite complete. Trigger Actions filter events by attribute, send different events to different people, and support multi-step escalation and acknowledgment. If your company runs only Zabbix, its built-in alert management covers most needs. But Zabbix is a relatively closed system and isn't well suited as a single entry point for many monitoring tools.
Alertmanager was designed from the start to serve more than Prometheus, and it offers a unified alert-receiving interface. But it has no model of people, so it can't handle schedules, acknowledgment, escalation, or comments. It's a middle component in the alert pipeline, not a company-wide on-call platform.
Neither tool was built for incident response. That's what the next five boundaries cover.
Five boundaries
Boundary 1: From receivers to schedules
Alertmanager routes eventually send alerts to a receiver, such as email, a webhook, PagerDuty, Opsgenie, or Slack. But on-call cares most about who should get the alert right now, and that's not a static list.
The same service might notify the development on-call during weekday hours, the SRE primary and backup at night, and a dedicated group on weekends. Critical services may need a primary and a backup on duty at once. When someone takes leave, you need a swap, and rotations should stay fair.
Flashduty schedules connect incidents to people. Rotations can run hourly, daily, weekly, or monthly. You can configure day and night shifts, primary and backup roles, date masks, swaps, and fair rotation. Dispatch policies can notify whoever is on call in a schedule, or only the primary or the backup. That way, "who's responsible today" isn't hard-coded in a receiver.
Boundary 2: From sending notifications to automatic escalation
Sending an alert doesn't mean anyone responds. The most dangerous case is an alert that went out and that nobody acknowledged. People in the chat saw it, each assumed someone else would handle it, and the incident dragged on.
Flashduty dispatch policies set trigger conditions, recipients, notification methods, delay windows, templates, and escalation rules. Escalation can trigger on "not closed" or "not closed and not acknowledged," moving to the next stage after a set time. Recipients can be schedules, teams, people, or a mix. Methods include phone, SMS, email, app push, IM direct messages, and group chats.
For example, a severity=critical payment alert could follow these rules:
- Notify the primary payment SRE first.
- If nobody acknowledges it in 10 minutes, escalate to the backup.
- If it isn't closed in 30 minutes, escalate to the payment development owner.
- Send lower-severity Warning alerts only to the IM group, with no phone calls.
If you keep all of this in Alertmanager config, it soon becomes a set of YAML conventions that are hard to audit. In an on-call platform, dispatch, notification, acknowledgment, and escalation sit on one traceable path.
Boundary 3: From alert to incident
Alertmanager handles alerts. An on-call platform handles incidents.
A real incident usually involves several alerts. First the API error rate rises, then the database connection pool runs out, then the service goes down, and finally recovery notices arrive. The responder needs to handle one incident, "payment service unavailable," not each alert on its own.
In Flashduty, a raw notification from a monitoring system is an event. Events trigger alerts, and similar alerts group into an incident. The incident is what you work on: you can dispatch, notify, acknowledge, snooze, close, merge, and review it. Noise reduction happens between alerts and incidents; see the noise reduction docs for details.
Alertmanager also groups, silences, and inhibits. The difference is that an on-call platform applies noise reduction to the incident. Dispatch, acknowledgment, escalation, timelines, and metrics then build on that incident.
Boundary 4: From chat messages to collaboration you can act on
Many teams send Alertmanager alerts to Feishu, DingTalk, WeCom, or Slack groups. That's easy to set up and easy to lose control of. Chat messages notify people, but they don't manage state. Once a message scrolls away, nobody knows whether anyone is handling it. Someone replies "I'll look," but the system has no acknowledgment state.
In Flashduty, you can acknowledge incidents from the console, IM app messages, or a voice call. At the end of a voice alert, you press a key to acknowledge. IM message cards offer actions such as acknowledge and close. The incident detail page records a timeline of triggers, dispatch, notifications, acknowledgment, snoozes, closure, and comments.
Incident response has to answer more than who got the message. It also has to answer who took over, what the current state is, who owns the next step, whether it escalated, and whether you can trace it afterward.
Boundary 5: From config files to data-driven management
Alertmanager config tells you how alerts are routed. It can't tell you whether your team's response is getting better. SRE leads usually need answers like these:
- How many incidents happened this month?
- Which services, teams, or collaboration spaces have the most alerts?
- What are MTTA and MTTR?
- Which incidents were never acknowledged?
- Who gets interrupted most by SMS, calls, and app push?
- Do alerts cluster in work hours, rest hours, or sleep hours?
- Which alert checks and alert objects fire most?
Flashduty analytics shows incident data by team, collaboration space, person, and more. Metrics include mean time to acknowledge (MTTA), mean time to resolve (MTTR), response rate, response effort, and interruption count. You can split time into work, rest, and sleep periods. Global views show the top 20 alert checks and alert objects, with CSV export.
With data, your team can see which rule, service, or schedule to improve. You can also see which alerts consume the most response time.
Connect Alertmanager to Flashduty
Alertmanager pushes alerts to Flashduty through a Webhook receiver. The Flashduty Prometheus integration supports Alertmanager 0.16.0 or later.
Create a Prometheus integration in Flashduty and copy its push URL. Then add a Webhook receiver to Alertmanager's receivers:
receivers:
- name: 'flashcat'
  webhook_configs:
  - url: '<your integration push URL>'
    send_resolved: true
To send alerts to Flashduty by default, set the receiver in route:
route:
  receiver: 'flashcat'
To leave your existing notification channels alone, put the Flashduty receiver in a child route. Start with a subset of services or severities.
Flashduty supports dedicated and shared integrations. A dedicated integration delivers alerts straight to one collaboration space. A shared integration uses routing rules based on the payload to deliver alerts to different collaboration spaces.
Labels such as severity on Prometheus alerts map to Flashduty severities; for example, critical maps to Critical. For the full mapping rules, see the Prometheus integration docs.
After that, you don't need to replace Prometheus or give up Alertmanager. Alertmanager acts as the upstream alert source, and Flashduty handles the response.
Validate with a 14-day trial
Don't evaluate an on-call platform from a feature list alone. Running real Prometheus alerts through it tells you more:
- Pick one business service and connect the Alertmanager webhook.
- Confirm that Critical, Warning, Info, and other severities map correctly.
- Create a collaboration space and a schedule for the service.
- Configure dispatch: phone or SMS for Critical, IM only for Warning.
- Configure escalation for unacknowledged incidents, for example, to the backup after 10 minutes.
- Turn on rule-based or intelligent grouping, and check that duplicate alerts join the same incident.
- Trigger a test alert and verify delivery through IM, phone, SMS, and the app.
- Acknowledge, snooze, and close the incident from IM or the console.
- Check the incident timeline to confirm it records notification, acknowledgment, and closure.
- Review incident count, MTTA, MTTR, response rate, and interruption count in analytics.
If all 10 steps work, you can tell whether Alertmanager is enough. For small teams, Alertmanager may be the right fit. For multiple teams, 24/7 on-call, critical services, and complex notification paths, an on-call platform fits better.
To start a trial, keep Prometheus and Alertmanager and send your alerts to the Flashduty console.
References
- Prometheus Alertmanager documentation: deduplication, grouping, routing, silencing, inhibition, and high availability.
- Prometheus alerting overview: how Prometheus alerting rules and Alertmanager divide the work.
- Flashduty Prometheus alert integration: connect the Alertmanager webhook to Flashduty.
- Flashduty noise reduction: the event, alert, and incident model, plus grouping, storm warnings, flapping detection, silences, and suppression.
- Flashduty dispatch policies: schedules, notification methods, delay windows, escalation rules, and primary/backup on-call.
- Flashduty analytics: MTTA, MTTR, response rate, response effort, interruption count, and data export.